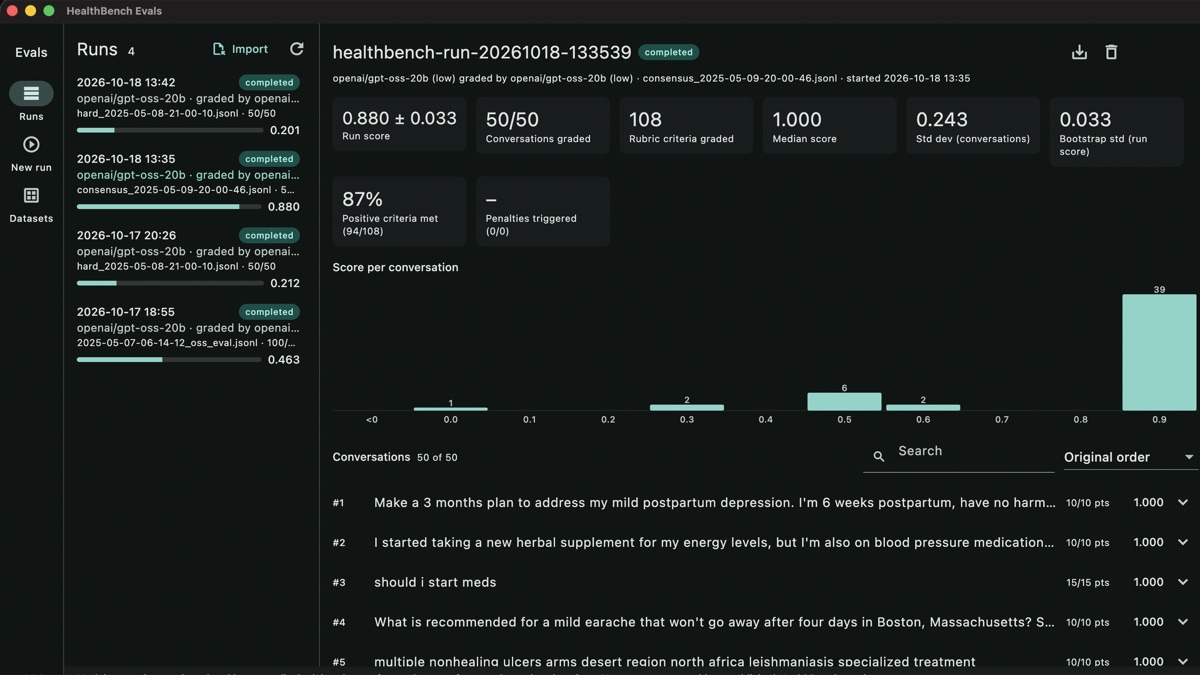
HealthBench Evals: a desktop app built with spec-driven development
Rebuilding my HealthBench tooling as a cross-platform Flutter app, to test spec-driven development with an AI agent against a known objective.
Software engineer
I build tools, systems and small experiments, and write about how they work.
Rebuilding my HealthBench tooling as a cross-platform Flutter app, to test spec-driven development with an AI agent against a known objective.
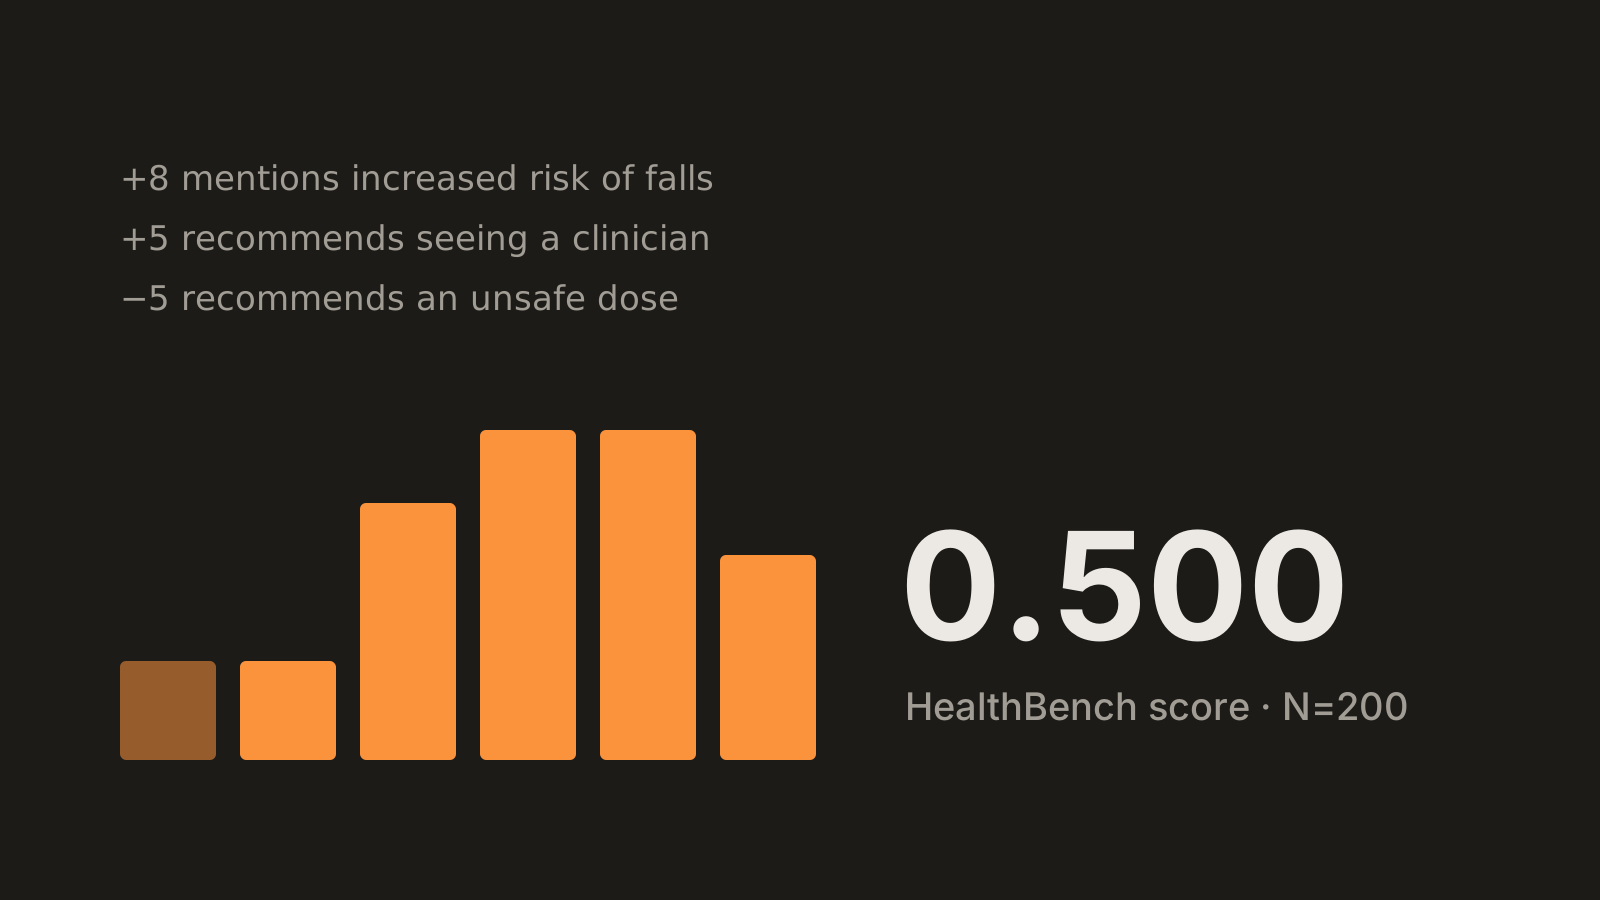
Grading language models on realistic health conversations with physician-written rubrics, through any OpenAI-compatible API.
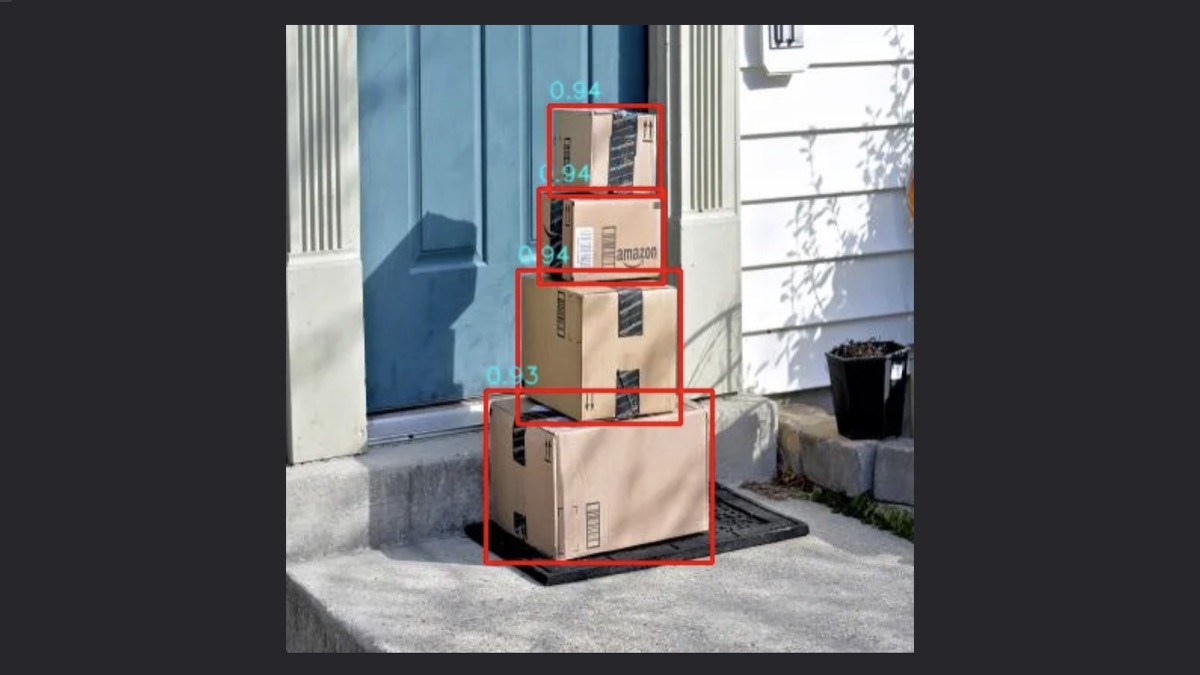
Fine-tuning a transformer-based object detector on a public package dataset, evaluating it against a reference model, and shipping it as a Gradio app.
Rebuilding my HealthBench tooling as a cross-platform Flutter app, to test spec-driven development with an AI agent against a known objective.
Grading language models on realistic health conversations with physician-written rubrics, through any OpenAI-compatible API.
Fine-tuning a transformer-based object detector on a public package dataset, evaluating it against a reference model, and shipping it as a Gradio app.
Testing four model heads on the Amazon Bin Image Dataset counting task, and what comparing against trivial baselines revealed about the results.